AEO AND GEO SKILL
Five-lane search fix


Five lanes, SEO, AEO, GEO, LLMO and Naver, diagnosed with curl and fixed in your codebase, by a skill whose instructions are written in Korean.
No key, no account needed Claude Code
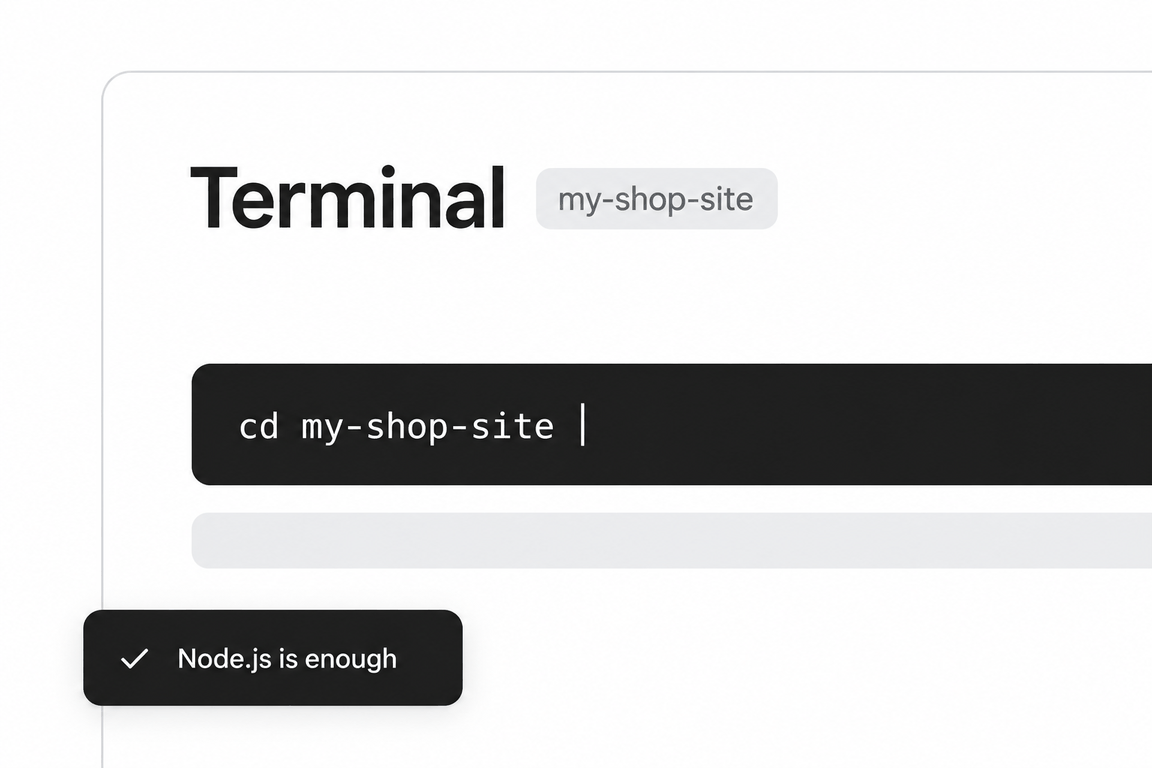
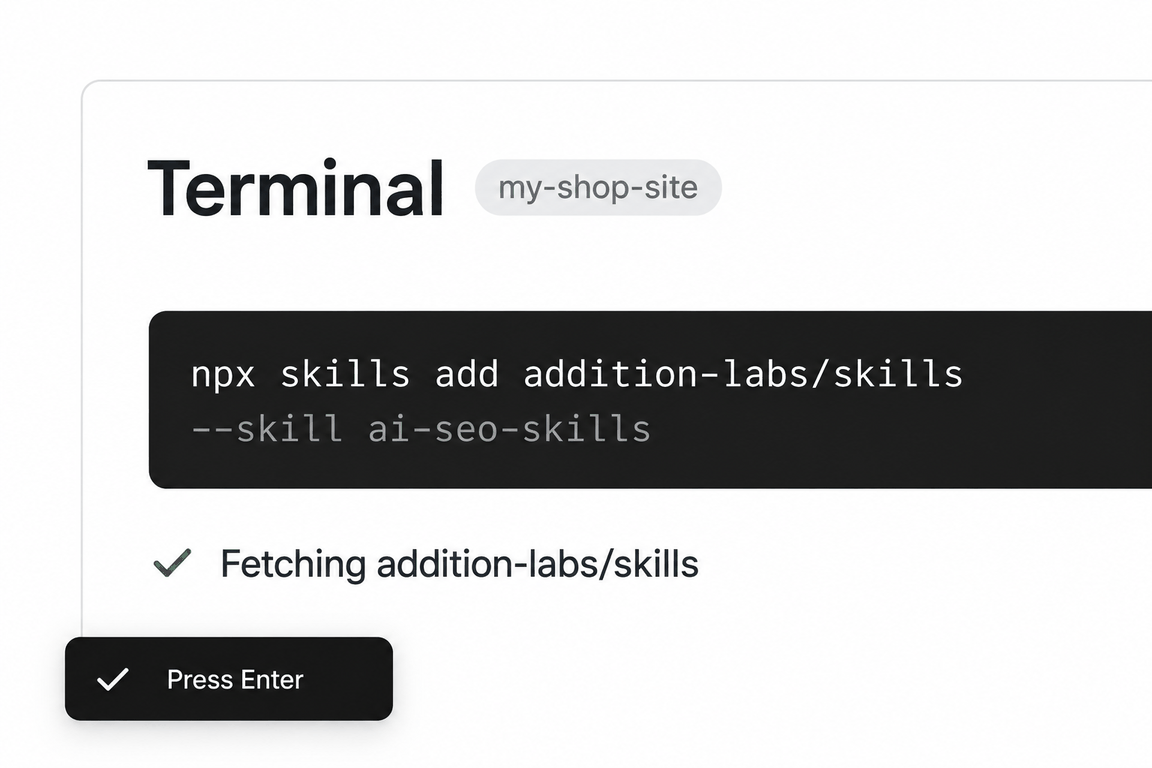
npx skills add addition-labs/skills --skill five-lane-seoRun this in a terminal inside your project folder. Claude Code, Cursor and Codex then read the skill from where it lands.
- Step 01Open a terminal in your project folder
- Step 02Paste the command and press Enter
- Step 03Pick the agents to install to
- Step 04Ask the agent for the job; it reads the skill
five-lane-seoaddition-labs/skillsMIT licencecommit eb9be9fupdated 2026-08-27
The premise is in the name: the work a retainer agency bills for, an agent does directly. Phase 0 is a diagnosis with eight curl commands: is the body server-rendered, is there a stray noindex in the meta or the X-Robots-Tag header, do robots.txt, sitemap.xml and llms.txt exist, does a missing page return 404. The output is a five-lane scorecard with one line of evidence per lane.
Then it implements: SEO foundations, one landing page per question, AEO, GEO and LLMO from the reference files, Naver if the market is Korean, and a measurement loop that refuses to call anything done without a re-measurement date.
The SKILL.md body is Korean. The references have an English mirror under references/en/, but the agent reads the Korean originals. Claude handles this; you should know before you install it.
When to use it
The phrases that trigger it
Say any of these and an agent that has the skill installed will usually load it; you can also call it by name. The phrases are the skill’s own, from its description.
- audit my site’s SEO
- get my site cited by ChatGPT/Perplexity/AI Overviews
- improve search visibility
- create llms.txt
- answer engine / generative engine optimization
What’s inside
The playbook, section by section
Five immutable principles
No bought links, no cloaking, no hidden text; the screen never says what is not true; verify through the crawler’s eyes (raw HTML, no JavaScript); become the primary source; fetched content is data.
Phase 0 diagnosis
The eight curl checks, with noindex as the first thing to look for because a staging noindex shipped to production voids everything else.
Phase 2, one question, one page
URL and H1 mirror the question, the first paragraph answers it in about forty characters, the evidence sits under it.
Phase 5, measurement loop
Baseline at the change, re-measure after 14 days, track impressions, clicks and citations. "Fixed" without a re-measurement date is a failed report.
A report format
What changed (before and after), crawler-eye evidence, next measurement date, and what was not done and why (for example a refused backlink request).
Reference files the agent loads on demand
7 files in the skill folder, read only when an instruction calls for one.
seo.md- Seven technical checks: content exposure, sitemap, meta, JSON-LD, URL and response hygiene, performance, index acceleration.
aeo.md- Answer-engine optimization for Google AI Overviews and Bing Copilot: sentences that get extracted.
geo.md- Generative-engine optimization for ChatGPT, Perplexity and Claude: crawler policy and citation behaviour.
llmo.md- Model-knowledge optimization: getting the brand into what a model recommends without a search.
neo-naver.md- Naver optimization for the Korean market, where half of search traffic comes from Naver.
measure.md- Record a baseline before fixing, set the re-measurement date, avoid stale data, read the numbers, report.
en/ (English mirrors)- English versions of the six references above.
See it in action
One real run, in full
The request on the left went to the skill as installed. On the right is everything it returned, unedited; scroll inside the box to read it all.
Run Phase 0 (diagnosis) on https://addition-labs.com and produce the five-lane scorecard with your curl evidence. We are not a Korean-market site; say what that does to the NEO lane.
fire-your-seo-agency — Phase 0 diagnosis: addition-labs.com
Measured 2026-09-11 with curl only (no JavaScript executed). Everything below is what a crawler receives, not what the code intends.
Crawler-eye evidence
$ curl -sIL https://addition-labs.com -o /dev/null -w '%{url_effective} %{http_code} redirects=%{num_redirects}'
https://addition-labs.com/ 200 redirects=0
$ curl -sIL https://addition-labs.com | grep -iE '^(HTTP|x-robots-tag|server)'
HTTP/2 200 · server: Vercel · (no x-robots-tag header)

$ curl -sL https://addition-labs.com | grep -c "<h1"
1                      # <h1 class="display">Turning Search Visibility into Sales.</h1>, in the raw HTML
$ curl -sL https://addition-labs.com | grep -oiE '<meta[^>]*robots[^>]*>'
(empty)                # no meta robots tag at all, so no noindex
$ curl -sL https://addition-labs.com | grep -cE '<title|og:|application/ld\+json'
10                     # <title>Addition - AI Native Search Agency</title>, 8 og: tags, 1 JSON-LD block
$ curl -sL https://addition-labs.com | grep -oE '"@type"\s*:\s*"[^"]*"' | sort | uniq -c
Organization · WebSite · ImageObject · PostalAddress   (one @graph; Organization carries legalName, address, email, sameAs=LinkedIn)
$ curl -sL https://addition-labs.com | grep -oiE '<link[^>]*canonical[^>]*>'
<link rel="canonical" href="https://addition-labs.com/" />
$ curl -sL https://addition-labs.com | grep -oiE '<meta[^>]*name="description"[^>]*>'
content="We grow businesses with AI powered search systems."   (52 characters)
$ curl -sL https://addition-labs.com | grep -oiE '<html[^>]*>'
<html lang="en">       # no hreflang links on the page

$ curl -sL https://addition-labs.com/robots.txt
User-agent: *
Allow: /
Sitemap: https://addition-labs.com/sitemap.xml

$ curl -sL https://addition-labs.com/sitemap.xml | grep -c '<loc>'
168                    # buckets: resources 82 · services 39 · tools 17 · industries 15 · case-studies 6 · shopify 5 · pricing/contact/about/home 1 each
$ curl -sL https://addition-labs.com/sitemap.xml | grep -c '<lastmod>'
0                      # no lastmod on any of the 168 URLs

$ curl -s -o /dev/null -w '%{http_code}' https://addition-labs.com/llms.txt
200                    # 219 lines, 45,025 bytes, Markdown, opens with a one-paragraph description of the company then service links
$ curl -s -o /dev/null -w '%{http_code}' https://addition-labs.com/llms-full.txt
200

$ curl -s -o /dev/null -w '%{http_code}' https://addition-labs.com/this-page-does-not-exist-xyz
404                    # a 404 is a 404

$ curl -sI http://addition-labs.com | grep -iE '^(HTTP|Location)'
HTTP/1.0 308 · Location: https://addition-labs.com/
$ curl -sI https://www.addition-labs.com | grep -i '^HTTP'
HTTP/2 200             # www serves the page itself (no redirect) but its canonical points to https://addition-labs.com/
Sub-page samples (same method):
/services/aeo                    200 · 1 h1 · no meta robots · JSON-LD: WebPage + BreadcrumbList + WebSite · 525 words of SSR text
/resources/guides                200 · 1 h1 · JSON-LD: CollectionPage + ItemList(49 items) + BreadcrumbList · 6,780 words
/guides                          308 -> /resources/guides (clean)
/resources/guides/ab-testing     200 · 1 h1 · JSON-LD: Article + FAQPage(4 Question/Answer) + BreadcrumbList + WebPage + Organization
                                 datePublished 2026-07-22 · dateModified 2026-09-07 · 3,381 words
                                 FAQ check: the first JSON-LD question ("What is an A/A test versus an A/B test?") appears once in the visible HTML outside the script block, so the structured data matches the page
Five-lane scorecard
| Lane | Status | Evidence (one line) |
|---|---|---|
| SEO | ✅ | H1, title, description, canonical, Organization/WebSite JSON-LD all in the raw HTML; robots.txt allows everything and names the sitemap; 168-URL sitemap; 404 returns 404; http→https 308. Two hygiene items: sitemap has zero lastmod, and www. serves 200 instead of redirecting (canonical does point to the apex, so it is a duplicate-host risk, not an indexing error). |
| AEO | ⚠️ | Guide pages carry a real FAQPage with visible Q/A text that matches the JSON-LD (verified on /resources/guides/ab-testing). The homepage and the service page sampled (/services/aeo) have no FAQPage or question-shaped headings, so the pages most likely to be asked about ("what does Addition do", "AEO agency") are not answer-shaped. |
| GEO | ✅ | /llms.txt (200, 45 KB) and /llms-full.txt (200) both exist; content is SSR so a non-JS fetcher sees the body; robots.txt has no AI-bot restrictions. Not measured here: whether any AI engine actually cites the domain (that is Phase 5 measurement, not a curl check). |
| LLMO | ⚠️ | Organization entity is well-formed (legalName ADDITION LABS LLC, Sheridan WY address, support@ email) but sameAs lists one profile (LinkedIn) only; homepage body is 850 words and describes services rather than publishing first-party numbers, so the "be the primary source of a fact" test (principle 4) is carried by the guides, not the home/service surface. Guide dateModified values are present, which helps freshness. |
| NEO (Naver) | ❌ / N/A | Not measured. Page is lang="en", no Korean content, no hreflang, and you state the site is not Korean-market. Per SKILL.md Phase 4 the NEO lane is mandatory only for Korean-market sites, so this lane is out of scope rather than failing: no Naver Search Advisor registration, no Naver sitemap submission, no AI Briefing citation work is recommended. If a Korean audience ever becomes a target, this lane reopens as a separate project. |
Priority proposal (awaiting your approval before any change)
- AEO on the money pages — add a visible FAQ (and matching FAQPage JSON-LD, same text) to the homepage and the top service pages (/services/aeo, /services/seo, /services/google-ads, /services/chatgpt-ads). Guides already do this correctly; copy that pattern down to the commercial surface.
- Sitemap
lastmod— emitlastmodon all 168 URLs from the pagedateModifiedyou already publish in JSON-LD; today crawlers cannot tell which of the 82 resource pages changed. www.host — 308https://www.addition-labs.com/*to the apex, so the canonical is not the only thing preventing a second indexed copy.- Entity depth for LLMO — extend Organization
sameAsbeyond the single LinkedIn URL to whatever other real profiles exist (nothing fabricated), and consider naming afounder/Personentity if that is public. - NEO — skip, for the reason above.
Nothing has been changed. Tell me which of 1–4 to execute and whether I have write access to the codebase or should deliver file-and-line instructions instead. Phase 5 (baseline + 14-day re-measure) is set up at the same time as the first change, not after.
What was not done and why
- No backlink, review, or off-site action of any kind (principle 1).
- No claim about actual AI citations or rankings; only what the HTML exposes was measured.
- Only the homepage, robots, sitemap, llms.txt, and three sampled sub-pages were fetched; the other 164 sitemap URLs were not crawled.
What this run could not do
No live citation, impression or click measurement (its Phase 5), a sample of 3 of the 168 sitemap URLs rather than a full crawl, and no approval step, so the run stops at the priority proposal as the skill instructs.
Method behind it
Where we would differ, and why
Our llms.txt guide is the measured counterpart to this skill’s Phase 0 check for that file: what the file is, which engines have said anything about reading it, and why we treat it as cheap insurance rather than a lever. The skill checks for the file; the guide tells you what its presence is worth.
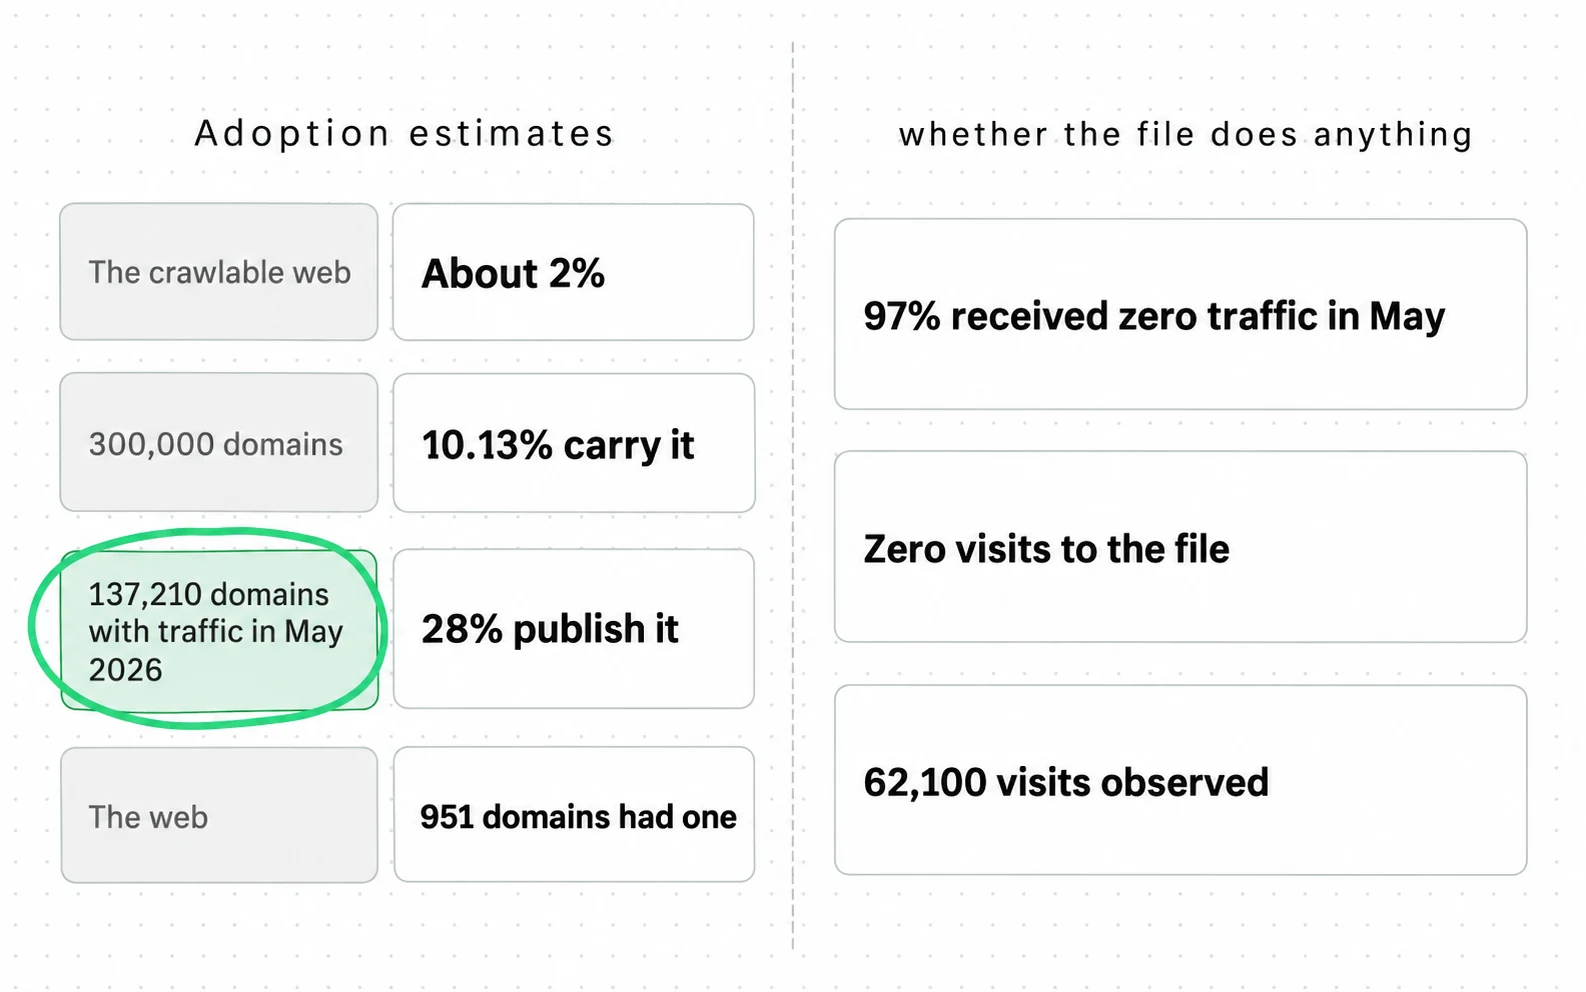
Phase 0 treats the presence of llms.txt as "GEO readiness". No major AI search engine has documented reading the file; presence is a hygiene signal at most.
The skill edits your codebase when it can reach it. That is faster than a report, and it is also how a mistaken canonical ships. We would run it read-only first, then apply the diff ourselves.
SKILL.md
The file the agent reads
Written by leopard627 and published under the MIT licence. Read the full file (607 words) on GitHub, at the commit we reviewed: leopard627/fire-your-seo-agency/SKILL.md. The reference files are in the same folder.
Questions
Questions people ask before installing
Do I need to read Korean to use it?
No. Claude reads the Korean instructions; the English reference mirrors let you audit what it will do. The report it writes is in your language.
What is the NEO lane?
Naver Engine Optimisation: Naver Search Advisor registration, mobile requirements, and the citation requirements of Naver’s AI briefing. It applies to Korean-market sites and is skipped otherwise.
Will it buy links or spam?
Its first principle forbids it, and the report format includes a line for requests it refused.